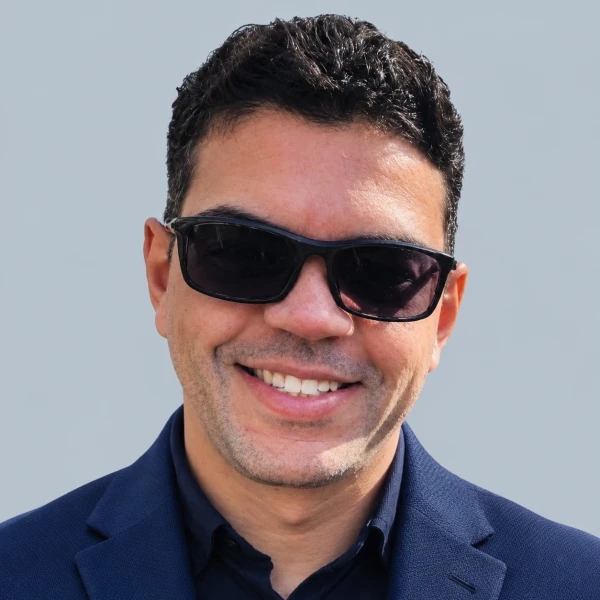
Bruno Souza
Software Engineer, Acuru | Ireland
Talk
The Vector Database We Didn't Buy: Source Ingestion on Node.js and Postgres
Your product needs search that understands meaning, and the usual answer is a new database. This talk explains what a vector database does and how far the Postgres you already run can take you with pgvector. We cover embeddings and distance metrics, how IVFFlat and HNSW indexes work and how to tune recall (probes, ef_search), and the SQL and Node.js code for a semantic query. Then three production lessons: the filtering trap that silently returns fewer rows once an index is added (and iterative index scans in pgvector 0.8), hybrid search with Reciprocal Rank Fusion, and the levers to pull before scale forces a dedicated store. It closes with a real source-ingestion library built on one Postgres table.
For backend and full-stack developers, especially Node.js, who are adding AI or semantic search features and want to decide on a vector store with numbers instead of hype.
About Bruno Souza
Learn from the Best Speakers 2026
Companies that support our community
Our Sponsors 2026
By becoming a sponsor of AI Poland, you gain a unique opportunity to showcase your company and products to hundreds of forward-thinking developers, engineers, and AI practitioners from across Europe.
This kind of exposure can drive meaningful interest in your solutions, help you connect with new business partners, and attract top tech talent.
To learn more about our sponsorship opportunities, please fill in the form.
Gold Sponsor
Gold Sponsor
Silver Sponsor
Silver Sponsor
Special Sponsor
Special Sponsor
Special Sponsor
Special Sponsor
Special Sponsor
ngGirls Sponsor
Stay in the loop Join our mailing list
Sign up to receive updates about AI Poland, including workshops, speaker announcements, ticket releases, AI Awards, expert interviews, CFP details, and other exclusive content. We won’t spam you — only thoughtfully curated updates we believe you’ll find truly valuable. You can unsubscribe at any time. More information available here.
- No spam
- Unsubscribe anytime
- Only the good stuff